Vineet Jain

Vineet Jain

I’m a Ph.D. candidate in Computer Science at McGill University and Mila – Quebec AI Institute, advised by Siamak Ravanbakhsh. I’m also a research scientist intern with the Consumer Agents team at Meta Superintelligence Labs in London, where I work on post-training and reinforcement learning for long-horizon agents.

In summer 2026, I interned with the Paradigms of Intelligence team at Google Research, where I built a language model controller that uses feedback to guide open-ended discovery.

My goal is to build agents that reason about their environment, learn through interaction, and generalize to unfamiliar tasks. I draw on reinforcement learning, probabilistic inference, and generative modeling to study language model reasoning, inference-time search, and open-ended discovery.

Previous experience

Before Google, I worked on diffusion-based sampling of molecular conformations at Valence Labs. At the Bosch Center for Artificial Intelligence, I studied how models generalize across domains when the training data is imbalanced.

I earned an M.S. in Machine Learning at Carnegie Mellon University and completed a B.Tech. in Electronics and Electrical Communication Engineering and an integrated M.Tech. in Visual Information Processing and Embedded Systems at IIT Kharagpur, with a minor in Computer Science.

As an undergraduate, I interned with Yoshua Bengio at Mila and Wulfram Gerstner at EPFL.

Selected Publications

* Equal contribution

Recursive Self-Aggregation Unlocks Deep Thinking in Large Language Models

Siddarth Venkatraman*, Vineet Jain*, Sarthak Mittal*, Vedant Shah, Johan Obando-Ceron, Yoshua Bengio, Brian R. Bartoldson, Bhavya Kailkhura, Guillaume Lajoie, Glen Berseth, Nikolay Malkin, Moksh Jain

Preprint (revised 2026)

Project PDF Code
Summary

Recursive Self-Aggregation uses additional inference compute to improve language model reasoning. It repeatedly asks the model to combine subsets of candidate solutions, carrying useful intermediate steps forward across iterations. The revised preprint reports gains on reasoning benchmarks including ARC-AGI-2 and introduces reinforcement learning to train models to aggregate solutions.

BibTeX
@misc{venkatraman2026recursive,
  title={Recursive Self-Aggregation Unlocks Deep Thinking in Large Language Models},
  author={Venkatraman, Siddarth and Jain, Vineet and Mittal, Sarthak and Shah, Vedant and
    Obando-Ceron, Johan and Bengio, Yoshua and Bartoldson, Brian R. and Kailkhura, Bhavya and
    Lajoie, Guillaume and Berseth, Glen and Malkin, Nikolay and Jain, Moksh},
  year={2026},
  eprint={2509.26626v2},
  archivePrefix={arXiv},
  url={https://arxiv.org/abs/2509.26626v2}
}
RSA diagram

A Comedy of Estimators: On KL Regularization in RL Training of LLMs

Vedant Shah*, Johan Obando-Ceron*, Vineet Jain*, Brian R. Bartoldson, Bhavya Kailkhura, Sarthak Mittal, Glen Berseth, Pablo S. Castro, Yoshua Bengio, Esmeralda S. Whitammer, Moksh Jain, Siddarth Venkatraman, Aaron Courville

COLM 2026

arXiv PDF
Summary

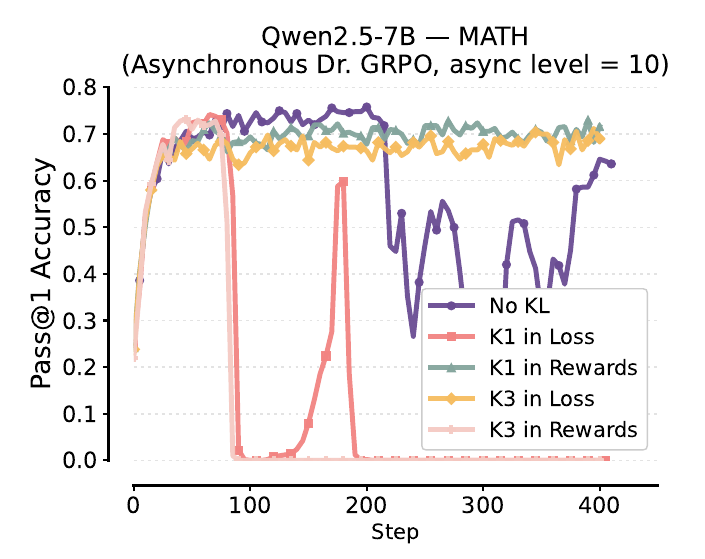
We study how choices about estimating reverse-KL regularization affect reinforcement learning for language models. We identify which estimator configurations give biased gradients and test their effects on training stability and reasoning performance across several model families.

BibTeX
@inproceedings{shah2026comedy,
  title={A Comedy of Estimators: On {KL} Regularization in {RL} Training of {LLMs}},
  author={Shah, Vedant and Obando-Ceron, Johan and Jain, Vineet and Bartoldson, Brian R. and
    Kailkhura, Bhavya and Mittal, Sarthak and Berseth, Glen and Castro, Pablo S. and Bengio, Yoshua and
    Whitammer, Esmeralda S. and Jain, Moksh and Venkatraman, Siddarth and Courville, Aaron},
  booktitle={Conference on Language Modeling},
  year={2026}
}
Pass@1 accuracy during asynchronous training with different reverse-KL configurations

Diffusion Tree Sampling: Scalable inference-time alignment of diffusion models

Vineet Jain, Kusha Sareen, Mohammad Pedramfar, Siamak Ravanbakhsh

NeurIPS 2025

Project PDF Code
Summary

Diffusion Tree Sampling casts inference-time alignment as a search problem. It reuses rewards from earlier generations to update value estimates along the denoising trajectory. The sampling variant converges to the reward-aligned target distribution as rollouts increase, while the greedy variant searches for high-reward samples. The experiments cover class-conditional image generation, text-to-image generation, and language completion.

BibTeX
@inproceedings{jain2025dts,
  title={Diffusion Tree Sampling: Scalable inference-time alignment of diffusion models},
  author={Jain, Vineet and Sareen, Kusha and Pedramfar, Mohammad and Ravanbakhsh, Siamak},
  booktitle={Advances in Neural Information Processing Systems},
  volume={38},
  year={2025},
  doi={10.52202/085713-4871}
}

Sampling from Energy-based Policies using Diffusion

Vineet Jain, Tara Akhound-Sadegh, Siamak Ravanbakhsh

RLC 2025 · Generative Models for Robot Learning Workshop, ICLR 2025

arXiv PDF
Abstract

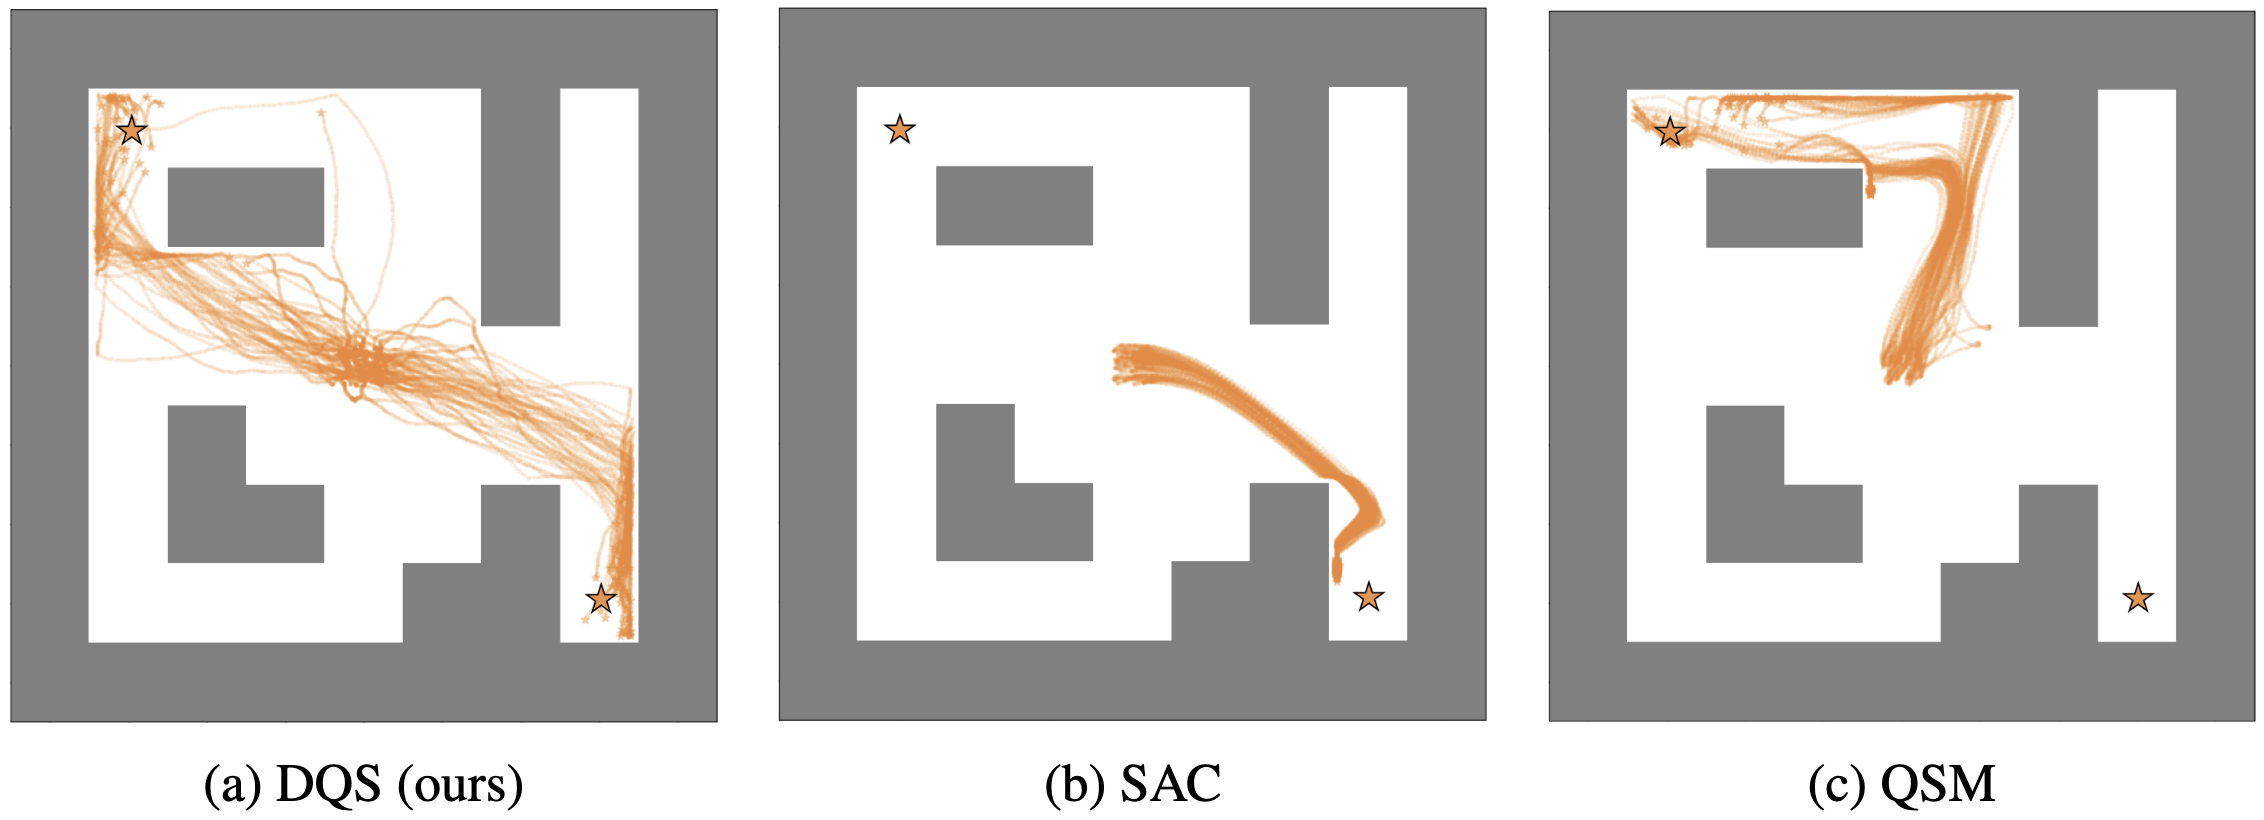
Energy-based policies offer a flexible framework for modeling complex, multimodal behaviors in reinforcement learning (RL). In maximum entropy RL, the optimal policy is a Boltzmann distribution derived from the soft Q-function, but direct sampling from this distribution in continuous action spaces is computationally intractable. As a result, existing methods typically use simpler parametric distributions, like Gaussians, for policy representation - limiting their ability to capture the full complexity of multimodal action distributions. In this paper, we introduce a diffusion-based approach for sampling from energy-based policies, where the negative Q-function defines the energy function. Based on this approach, we propose an actor-critic method called Diffusion Q-Sampling (DQS) that enables more expressive policy representations, allowing stable learning in diverse environments. We show that our approach enhances exploration and captures multimodal behavior in continuous control tasks, addressing key limitations of existing methods.

BibTeX
@article{jain2025sampling,
  title={Sampling from Energy-based Policies using Diffusion},
  author={Jain, Vineet and Akhound-Sadegh, Tara and Ravanbakhsh, Siamak},
  journal={Reinforcement Learning Journal},
  volume={6},
  pages={2291--2307},
  year={2025}
}
Sampling from Energy-based Policies using Diffusion diagram

Learning to Reach Goals via Diffusion

Vineet Jain, Siamak Ravanbakhsh

ICML 2024 · Generative Models for Decision Making Workshop, ICLR 2024

PDF
Abstract

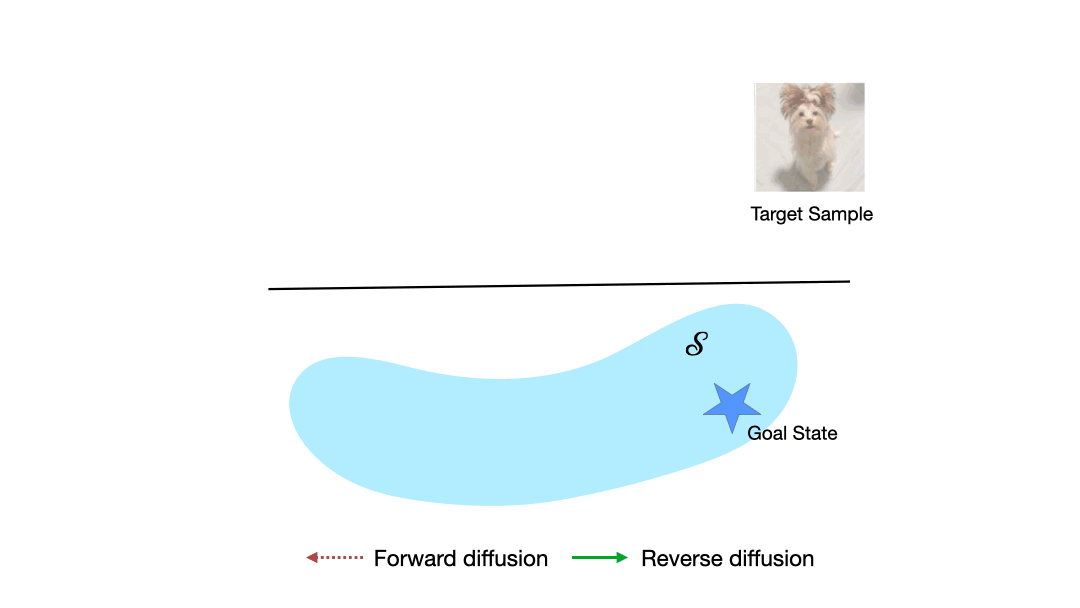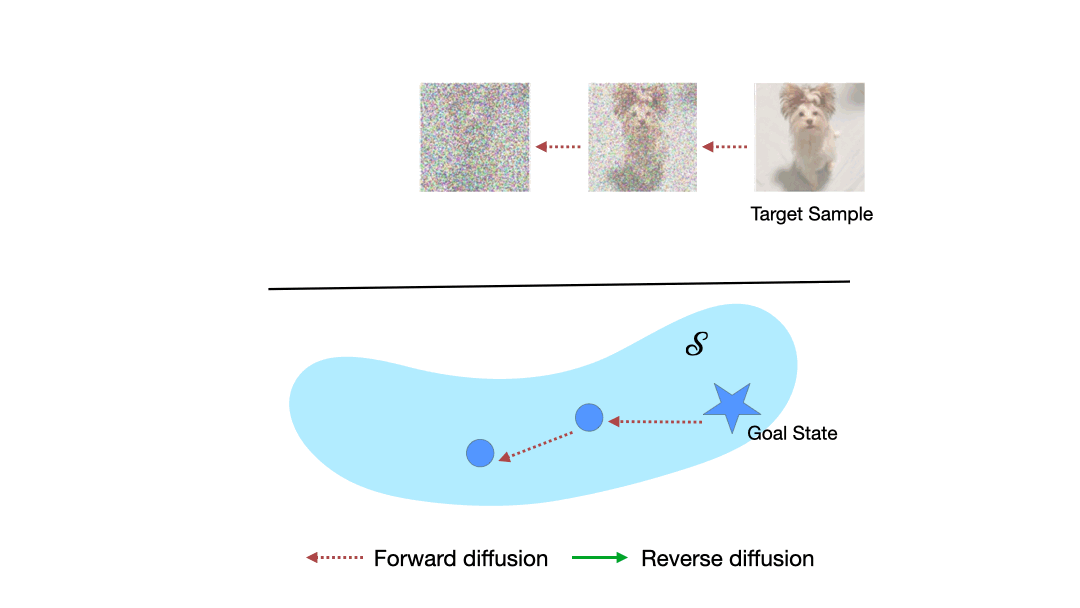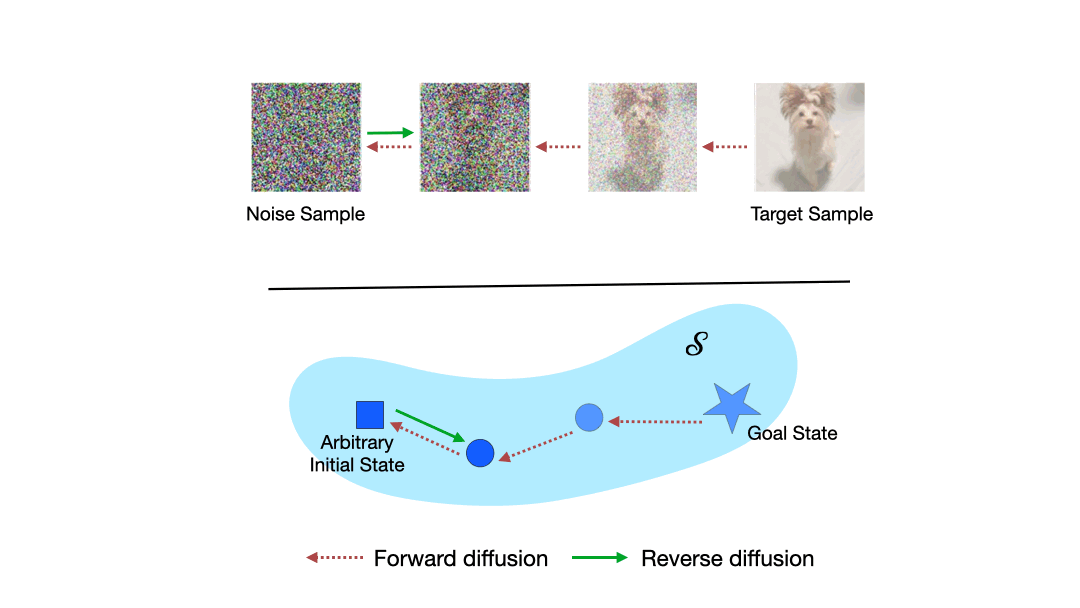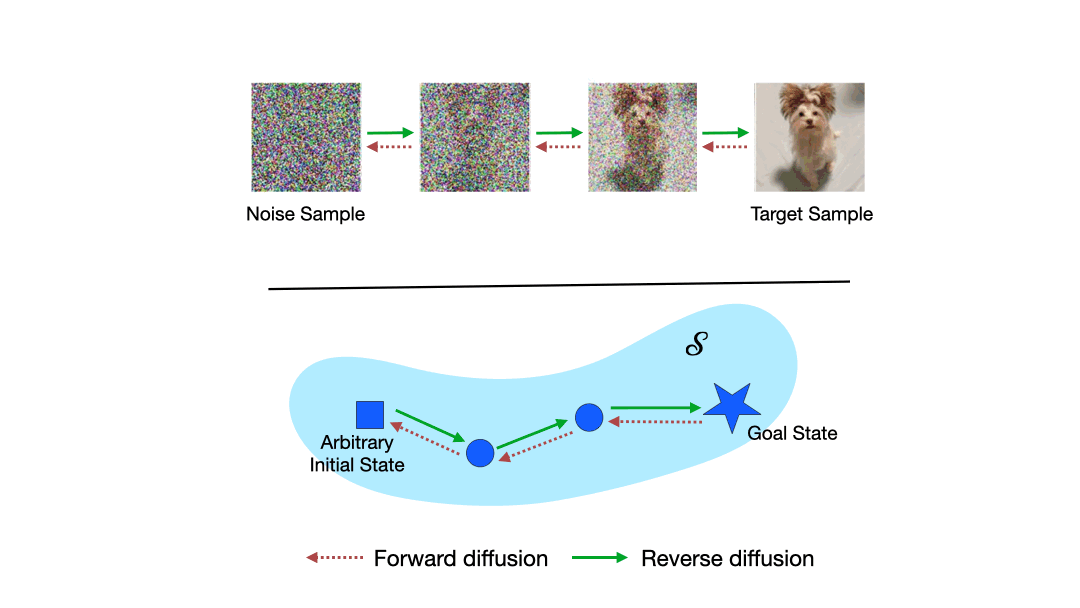
Diffusion models are a powerful class of generative models capable of mapping random noise in high-dimensional spaces to a target manifold through iterative denoising. In this work, we present a novel perspective on goal-conditioned reinforcement learning by framing it within the context of diffusion modeling. Analogous to the diffusion process, where Gaussian noise is used to create random trajectories that walk away from the data manifold, we construct trajectories that move away from potential goal states. We then learn a goal-conditioned policy analogous to the score function. This approach, which we call Merlin, can reach predefined or novel goals from an arbitrary initial state without learning a separate value function. We consider three choices for the noise model to replace Gaussian noise in diffusion - reverse play from the buffer, reverse dynamics model, and a novel non-parametric approach. We theoretically justify our approach and validate it on offline goal-reaching tasks. Empirical results are competitive with state-of-the-art methods, which suggests this perspective on diffusion for RL is a simple, scalable, and effective direction for sequential decision-making.

BibTeX
@inproceedings{jain2024learning,
  title={Learning to Reach Goals via Diffusion},
  author={Jain, Vineet and Ravanbakhsh, Siamak},
  booktitle={Proceedings of the 41st International Conference on Machine Learning},
  series={Proceedings of Machine Learning Research},
  volume={235},
  pages={21170--21195},
  year={2024}
}
Learning to Reach Goals via Diffusion animation

On Diffusion Modeling for Anomaly Detection

Victor Livernoche*, Vineet Jain*, Yashar Hezaveh, Siamak Ravanbakhsh

ICLR 2024 (Spotlight)

OpenReview PDF
Abstract

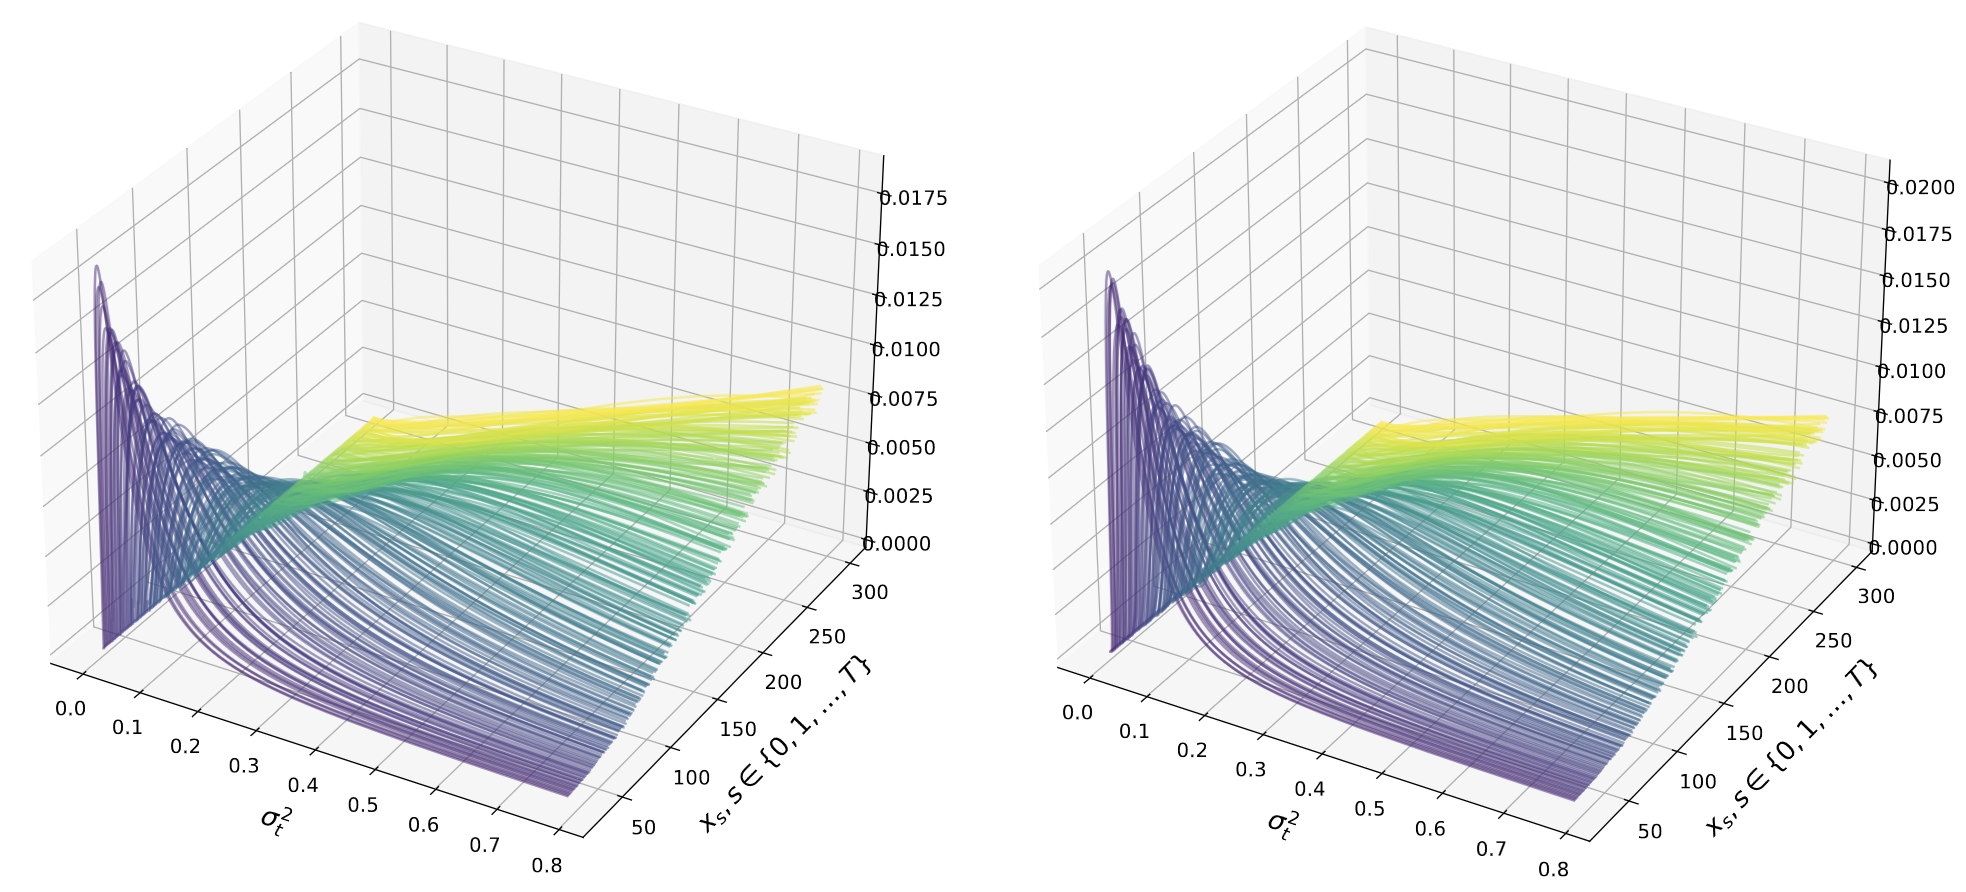
Known for their impressive performance in generative modeling, diffusion models are attractive candidates for density-based anomaly detection. This paper investigates different variations of diffusion modeling for unsupervised and semi-supervised anomaly detection. In particular, we find that Denoising Diffusion Probability Models (DDPM) are performant on anomaly detection benchmarks yet computationally expensive. By simplifying DDPM in application to anomaly detection, we are naturally led to an alternative approach called Diffusion Time Estimation (DTE). DTE estimates the distribution over diffusion time for a given input and uses the mode or mean of this distribution as the anomaly score. We derive an analytical form for this density and leverage a deep neural network to improve inference efficiency. Through empirical evaluations on the ADBench benchmark, we demonstrate that all diffusion-based anomaly detection methods perform competitively for both semi-supervised and unsupervised settings. Notably, DTE achieves orders of magnitude faster inference time than DDPM, while outperforming it on this benchmark. These results establish diffusion-based anomaly detection as a scalable alternative to traditional methods and recent deep-learning techniques for standard unsupervised and semi-supervised anomaly detection settings.

BibTeX
@article{livernoche2023diffusion,
  title={On Diffusion Modeling for Anomaly Detection},
  author={Livernoche, Victor and Jain, Vineet and Hezaveh, Yashar and Ravanbakhsh, Siamak},
  journal={arXiv preprint arXiv:2305.18593},
  year={2023}
}
Diffusion Modeling for Anomaly Detection diagram